- Python 72.6%
- TypeScript 21.8%
- PowerShell 1.4%
- Shell 1.4%
- JavaScript 1.3%
- Other 1.4%
 975e8649c1 ## Summary
A Wan2.1-T2V-1.3B render on a Kaggle T4 at a forced 8 GiB budget failed
at export with `ValueError: Expected numpy array with dtype uint8 but
got float32`. The log showed an untiled decode, then `decode ran out of
memory; retrying tiled at stock tile sizes`, then `video.stream_encode:
fallback (decoder restarted)`.
The decode retry did not corrupt the clip. Rebuilding Studio's real Wan
decode stack around the real Wan2.1 VAE (fp16 decode, fused VAE kernels,
untiled gate, OOM ladder and scope, stream encoder) reproduces that log
sequence line for line, but only when the latents reaching the VAE are
non-finite:
1. The fp16 untiled decode completes, with NaN output.
2. `_video_vae_half_decode` sees the non-finite output, moves the
decoder to fp32 for good, and reruns the decode untiled. That rerun is
the `decoder restarted` line. The warning it logs was dropped, because
the video load called `run_speed_layer` without a logger.
3. The fp32 untiled decode needs about twice the memory (8741 MiB
measured, against 4372 MiB for fp16 at 480x832x33) and runs out of
memory.
4. The OOM ladder retries tiled in fp32. The NaN latents give NaN
frames, and PyAV refuses them.
With finite latents, every OOM retry path returns finite frames close to
an untiled render.
Two more bugs came up along the way. The stream encoder's per-render
`decode` wrapper had no `__wrapped__`, which hid the decode chain:
- `diffusion_vae_oom` could not find the untiled-when-fits gate, so the
ladder retried tiled underneath it. The gate never recorded the OOM, so
every later render ran out of memory again.
- The OOM scope reinstalled itself above that wrapper after each decode.
The render then removed the wrapper, and the scope with it.
## Changes
- `video_stream_encode.py`: the Wan and H3 session `decode` wrappers
expose `__wrapped__`. The untiled gate now handles an untiled OOM during
a streamed render, and the scope stays installed. Kill switch:
`UNSLOTH_STUDIO_VIDEO_STREAM_ENCODE_CHAIN=0`.
- `diffusion_speed.py` (`_video_vae_half_decode`): when the latents
themselves are non-finite, the decoder stays in fp16 and does not rerun
in fp32 (fp32 cannot make NaN inputs finite). The finiteness check runs
only on the branch where the fp16 output is already non-finite. A
non-finite fp16 output from finite latents still reruns in fp32, as
before. Kill switch: `UNSLOTH_VIDEO_VAE_NONFINITE_INPUT_KEEP_FP16=0`.
- `video_frames.py` / `video.py`: `_encode_mp4` refuses float frames
that hold NaN or inf with `NonFiniteFramesError`. `video_failure_detail`
maps it to a fixed message ("The decoded video holds NaN or infinite
values, so it was not saved."). Before this change, every encoder path
ended in PyAV's dtype error on such frames. Finite frames are untouched,
and frames are never clamped.
- `video.py`: the video load passes its logger to `run_speed_layer`, as
the H3 path already does, so speed-layer warnings are logged.
- The untiled fit margin is unchanged. The fp16 estimate is 3895 MiB, or
6917 MiB with margin. The measured fp16 peak is 4372 MiB, which fits in
the 7207 MiB free. The miss arm (k13o_f1) decoded untiled at 7231 MiB
free. The OOM came from the fp32 rerun, which needs 8741 MiB.
## Results
Real Wan2.1-T2V-1.3B VAE with Studio's decode stack, 480x832, 33 frames,
on a local B200 with a per-process memory cap:
| case | main | this PR |
|---|---|---|
| no OOM, streamed | reference frames | bit-identical to main
(`torch.equal`), stream `valid` |
| untiled OOM (3.5 GB cap), streamed | ladder `retrying tiled at stock
tile sizes`; the next render OOMs again | gate `untiled decode ran out
of memory; decoding tiled`; the next render goes tiled without an OOM |
| retry frames vs untiled | PSNR 53.1 dB | identical to main's retry
frames; PSNR 53.1 dB, LPIPS (alex) mean 0.0003, max 0.0004 |
| NaN latents (5 GB cap) | fp32 rerun (`decoder restarted`), OOM, tiled
fp32, NaN float32 clip; export crashes in PyAV | fp16 kept, no rerun, no
OOM; export fails with the clear error |
## Tests
- New `tests/test_video_decode_oom_retry.py`, 10 tests:
- on main: 8 fail (6 on behaviour, 2 kill-switch tests on missing
attributes) and 2 pass (no-OOM bit-identity, and the fp32 rerun for
finite latents);
- on this branch: all 10 pass.
- Related suites on this branch (`test_video_stream_encode`,
`test_video_vae_untiled`, `test_diffusion_vae_oom*`,
`test_video_frames`, `test_diffusion_speed`, `test_diffusion_autoopt_*`,
`test_video_vae_fp16_decode`, `test_video_encode`, `test_video_nvenc`,
`test_video_stream_residency`, `test_vae_channels_last_3d`,
`test_video_vae_bf16_decode_rocm`): 3872 passed, 2 failed.
- The 2 failures are
`test_a_compiled_decode_runs_the_chunk_hook_as_one_eager_island[cpu]`
and
`test_execution_device_resolves_the_card_while_a_component_waits_on_the_host`.
Both fail the same way on main (a diffusers `pipeline_utils` import
error on this host).
## Limits
- Where the non-finite latents came from is not established. The crashed
arm was the only one that loaded the transformer from the float16 cast
cache. It was also the only arm that logged `video.wan_fused: fused fp16
modulation did not match the stock block`, which is what a NaN in the
stock block's output would cause. This points at the denoiser on that
load, not the decode, but it has not been reproduced.
- No real T4 run: the OOMs here come from a memory cap on a B200 and the
NaN latents are injected. The decode stack is the production code, and
the log sequence matches the Kaggle log line for line.
- The SDXL fp16 decode (`diffusion_vae_fp16.py`) has the same
fp32-rerun-on-NaN-input pattern. It is not changed here.
---------
Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com>
|
||
|---|---|---|
| .github | ||
| docker | ||
| images | ||
| scripts | ||
| studio | ||
| tests | ||
| unsloth | ||
| unsloth_cli | ||
| .gitattributes | ||
| .gitignore | ||
| .pre-commit-config.yaml | ||
| build.sh | ||
| cli.py | ||
| CODE_OF_CONDUCT.md | ||
| CONTRIBUTING.md | ||
| COPYING | ||
| install.ps1 | ||
| install.sh | ||
| LICENSE | ||
| MANIFEST.in | ||
| pyproject.toml | ||
| README.md | ||
| unsloth-cli.py | ||
Unsloth is the first desktop app to run and train models.
Features • Quickstart • Notebooks • Documentation
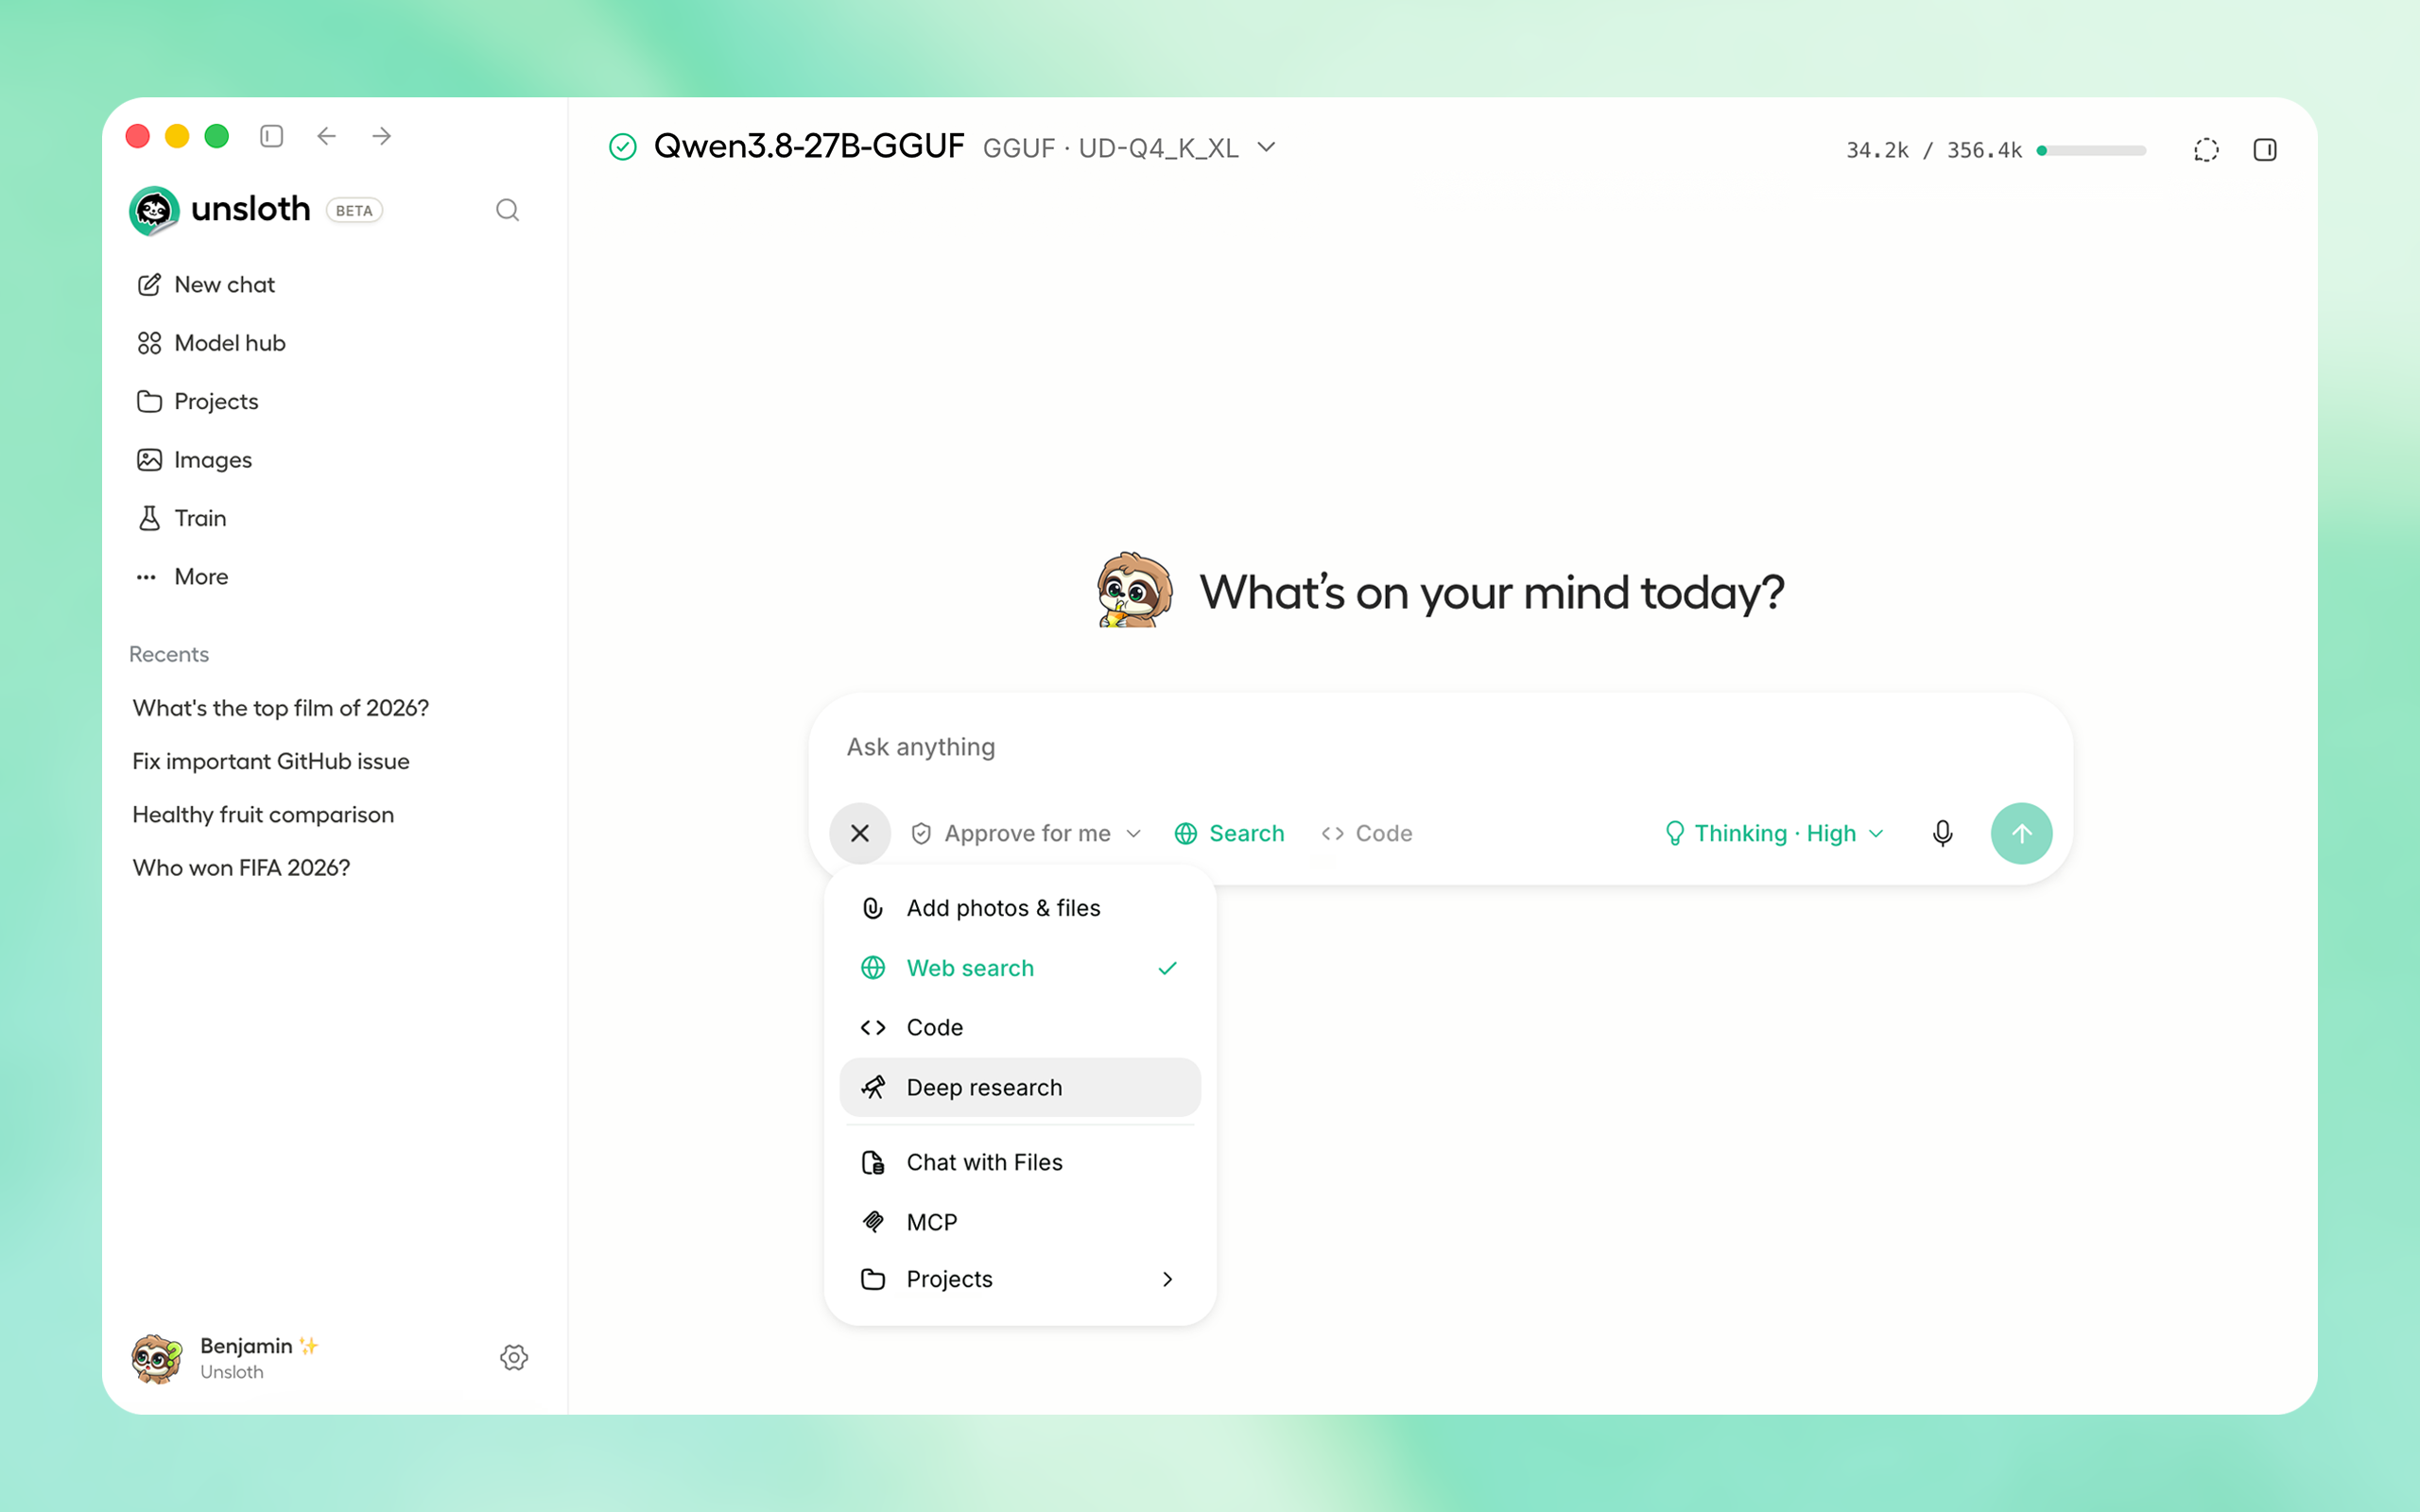
⚡ Get started
Download the native Unsloth Desktop app for your operating system:
| Platform | Link |
| Windows | Download |
| macOS | Download |
| Linux / Ubuntu (deb) | Download |
| Linux / Ubuntu (ARM64) (deb) | Download |
| Linux (AppImage) | Download |
| Windows (ARM64) | Download |
Download from Unsloth or GitHub Releases.
Or if you prefer to install manually:
macOS, Linux, WSL:
curl -fsSL https://unsloth.ai/install.sh | sh
Windows:
irm https://unsloth.ai/install.ps1 | iex
Docker:
The Unsloth Docker image unsloth/unsloth is available on Docker. Read guide.
Homebrew:
brew install --cask unsloth
Winget (Windows):
winget install --id UnslothAI.Unsloth -e
Community:
⭐ Features
Unsloth works on Windows, Linux, WSL and macOS. We support Multi GPU setups, NVIDIA, AMD, Intel GPUs, CPUs and the Vulkan backend.
Run & Build with AI
- Run and train LLMs, MLX, GGUF, diffusion, decision, embedding, audio models: Qwen3.8, GLM-5.3-Flash, Kimi K3, Qwen-Image-2.1, MiniMax-H3, DeepSeek-V4, Gemma 4.
- Agents & Tools: Use local models with Claude Code, Codex, and MCP, including tool calling and code execution.
- Search & RAG: Use private and unlimited web search, deep research, auto-compaction (rolling context window) and RAG.
- Image and video: Run and train image and video diffusion or multimodal models
- Remote & LAN: Access your local models from any device on LAN or remotely through secure Cloudflare HTTPS.
- Connect: Serve models through an OpenAI compatible API. Also connect your ChatGPT/Codex subscription and cloud providers
Train & Deploy
- Fine-tuning: Train LLMs, diffusion, decision, TTS, and embedding models 2× faster with 70% less VRAM with no accuracy loss
- Complete support: Supports reinforcement learning, LoRA, QLoRA, full fine tuning, pretraining, RL, GRPO, DPO, and FP8.
- Export & Deploy: Export or Deploy models including GGUF, NVFP4, FP8 and more formats.
- Datasets: Build datasets from PDFs, CSVs, DOCX files, and more with Data Recipes.
🚀 Unsloth Start
Unsloth Start connects Claude Code, Codex and other agents to local models with one command.
unsloth start claude --model unsloth/Qwen3.8-27B-GGUF:UD-Q4_K_XL
| Agent | Command |
|---|---|
| Claude Code | unsloth start claude |
| OpenAI Codex | unsloth start codex |
| Visual Studio Code | unsloth start vscode |
| DeepSeek Harness | unsloth start dsh |
| OpenCode | unsloth start opencode |
| Hermes Agent | unsloth start hermes |
| Pi | unsloth start pi |
| OpenClaw | unsloth start openclaw |
| Mistral Vibe | unsloth start vibe |
📥 Install
Unsloth can be used in three ways: Unsloth Desktop, the desktop app; Unsloth Studio, the web UI; or Unsloth Core, the code based version.
Unsloth Desktop (recommended)
| Platform | Link |
| Windows | Download |
| macOS | Download |
| Linux / Ubuntu (deb) | Download |
| Linux / Ubuntu (ARM64) (deb) | Download |
| Linux (AppImage) | Download |
| Windows (ARM64) | Download |
Unsloth Studio (web UI)
macOS, Linux, WSL:
curl -fsSL https://unsloth.ai/install.sh | sh
Windows:
irm https://unsloth.ai/install.ps1 | iex
Homebrew:
brew install --cask unsloth
Docker
Use our Docker image unsloth/unsloth. On Linux and Mac, set up GPU access once with
curl -fsSL https://raw.githubusercontent.com/unslothai/unsloth/main/docker/install_nvidia_toolkit.sh -o install_nvidia_toolkit.sh && sudo -E bash install_nvidia_toolkit.sh
For Windows instructions and more information, read our Unsloth Docker Guide.
Linux / WSL (Bash):
# for a public Cloudflare HTTPS link: use  -e UNSLOTH_STUDIO_SECURE=1  instead of -p 8000:8000, and  -p 127.0.0.1:8888:8888  instead of -p 8888:8888
docker run -d --name unsloth --gpus all --ipc=host \
  -p 8000:8000 -p 8888:8888 \
  -v "$PWD":/workspace/host \
  -v unsloth-workspace:/workspace \
  -v "$HOME/.cache/huggingface":/workspace/.cache/huggingface \
  -v unsloth-studio:/opt/unsloth-studio \
  unsloth/unsloth && docker logs -f unsloth
See Docker docs for more information. For notebooks only, use the unsloth/unsloth:core tag; all tags and options are on Docker Hub.
For AMD there is a separate image: unsloth/unsloth-rocm.
Launch
unsloth studio
HTTP Secure Deployment
unsloth studio --secure
Remote HTTPS & LAN Access
Server-side tools are on by default - so be careful! Keep your password safe, or use --disable-tools when exposing Unsloth.
Global HTTPS Access: Creates a free Cloudflare link that serves Unsloth - you can access the link globally (even on your phone!)
unsloth studio --secure
-H 0.0.0.0 and different ports also work:
unsloth studio -H 0.0.0.0 -p 8888
LAN Access (home network): Settings > API keys > LAN access
Password management & headless starts
Exposing Unsloth (--secure, --cloudflare, or a non-loopback -H) asks once at the terminal for a new admin password. Ctrl+C there aborts the launch rather than exposing the auto-generated one; set a password non-interactively instead, or use -H 127.0.0.1 to stay off the network.
Headless starts:
UNSLOTH_STUDIO_PASSWORD='your-strong-password' unsloth studio --secure # via env var
Reset your password:
unsloth studio reset-password
Developer, Nightly, Uninstall
To see developer, nightly and uninstallation etc. instructions, see advanced installation.
Unsloth Core (code-based)
Linux, WSL:
curl -LsSf https://astral.sh/uv/install.sh | sh
uv venv unsloth_env --python 3.13
source unsloth_env/bin/activate
uv pip install unsloth --torch-backend=auto
Windows:
winget install -e --id Python.Python.3.13
winget install --id=astral-sh.uv  -e
uv venv unsloth_env --python 3.13
.\unsloth_env\Scripts\activate
uv pip install torchao
uv pip install unsloth --torch-backend=auto
Install torchao first on Windows: --torch-backend looks for it only on the PyTorch index, which has no recent Windows torchao, so a one-step install silently resolves an old Unsloth.
AMD, Intel, DGX Spark, Blackwell:
See our Blackwell guide and DGX Spark guide.
To install Unsloth on AMD and Intel GPUs, follow our AMD Guide and Intel Guide.
📒 Free Notebooks
Train for free with our notebooks. Read our guide. Add dataset, run, then deploy your trained model.
| Model | Free Notebooks | Performance | Memory use |
|---|---|---|---|
| Unsloth Studio | ▶️ Start for free | ||
| Decision model (Qwen3.5-4B) | ▶️ Start for free | 1.5x faster | 60% less |
| Gemma 4 (E2B) | ▶️ Start for free | 1.5x faster | 50% less |
| Qwen3.5 (4B) | ▶️ Start for free | 1.5x faster | 60% less |
| gpt-oss (20B) | ▶️ Start for free | 2x faster | 70% less |
| Qwen3.5 GSPO | ▶️ Start for free | 2x faster | 70% less |
| gpt-oss (20B): GRPO | ▶️ Start for free | 2x faster | 80% less |
| Qwen3: Advanced GRPO | ▶️ Start for free | 2x faster | 70% less |
| embeddinggemma (300M) | ▶️ Start for free | 2x faster | 20% less |
| Llama 3.1 (8B) Alpaca | ▶️ Start for free | 2x faster | 70% less |
| Llama 3.2 Conversational | ▶️ Start for free | 2x faster | 70% less |
| Orpheus-TTS (3B) | ▶️ Start for free | 1.5x faster | 50% less |
- See all our notebooks for: Kaggle, GRPO, TTS, embedding & Vision
- See all our models and all our notebooks
- See detailed documentation for Unsloth here
📥 Advanced Installation
The below advanced instructions are for Unsloth Studio. For Unsloth Core advanced installation, view our docs.
Developer / Nightly / Experimental installs: macOS, Linux, WSL:
The developer install builds from the main branch, which is the latest (nightly) source.
git clone https://github.com/unslothai/unsloth
cd unsloth
./install.sh --local
unsloth studio -p 8888
To install into an isolated location, set UNSLOTH_STUDIO_HOME:
UNSLOTH_STUDIO_HOME="$PWD/.studio" ./install.sh --local
UNSLOTH_STUDIO_HOME="$PWD/.studio" unsloth studio -p 8888
Then to update:
cd unsloth && git pull
./install.sh --local
unsloth studio -p 8888
Developer / Nightly / Experimental installs: Windows PowerShell:
The developer install builds from the main branch, which is the latest (nightly) source.
git clone https://github.com/unslothai/unsloth.git
cd unsloth
Set-ExecutionPolicy -Scope Process -ExecutionPolicy RemoteSigned
.\install.ps1 --local
unsloth studio -p 8888
To install into an isolated location, set UNSLOTH_STUDIO_HOME:
$env:UNSLOTH_STUDIO_HOME="$PWD\.studio"; .\install.ps1 --local
$env:UNSLOTH_STUDIO_HOME="$PWD\.studio"; unsloth studio -p 8888
Then to update:
cd unsloth; git pull
.\install.ps1 --local
unsloth studio -p 8888
Advanced launch options
Skip PyTorch (GGUF-only mode):
curl -fsSL https://unsloth.ai/install.sh | UNSLOTH_NO_TORCH=1 sh
$env:UNSLOTH_NO_TORCH=1; irm https://unsloth.ai/install.ps1 | iex
Skip the post-install prompt that starts Unsloth (useful for automated installs):
curl -fsSL https://unsloth.ai/install.sh | UNSLOTH_SKIP_AUTOSTART=1 sh
$env:UNSLOTH_SKIP_AUTOSTART=1; irm https://unsloth.ai/install.ps1 | iex
Keep the install-time package cache under the Unsloth Studio directory instead of reusing an existing uv cache. Downloads are slower the first time, and an explicit UV_CACHE_DIR still wins over this:
curl -fsSL https://unsloth.ai/install.sh | UNSLOTH_ISOLATE_UV_CACHE=1 sh
$env:UNSLOTH_ISOLATE_UV_CACHE=1; irm https://unsloth.ai/install.ps1 | iex
For a local run the flag is --isolated-uv-cache:
./install.sh --local --isolated-uv-cache
.\install.ps1 --local --isolated-uv-cache
Discard the previous environment immediately when reinstalling, instead of keeping a copy until the new one works. A reinstall normally holds both at once, so it needs room for two; this needs room for one, at the cost of not being able to undo a failed install:
curl -fsSL https://unsloth.ai/install.sh | UNSLOTH_INSTALL_NO_ROLLBACK=1 sh
$env:UNSLOTH_INSTALL_NO_ROLLBACK=1; irm https://unsloth.ai/install.ps1 | iex
For a local run the flag is --no-rollback:
./install.sh --local --no-rollback
.\install.ps1 --local --no-rollback
Pinning the Python version:
curl -fsSL https://unsloth.ai/install.sh | UNSLOTH_PYTHON=3.12 sh
$env:UNSLOTH_PYTHON='3.12'; irm https://unsloth.ai/install.ps1 | iex
Install to a custom location with UNSLOTH_STUDIO_HOME:
curl -fsSL https://unsloth.ai/install.sh | UNSLOTH_STUDIO_HOME=/abs/path sh
$env:UNSLOTH_STUDIO_HOME='C:\path'; irm https://unsloth.ai/install.ps1 | iex
Point the frontend build at a corporate npm mirror/proxy with UNSLOTH_NPM_REGISTRY:
UNSLOTH_NPM_REGISTRY=https://artifactory.example.com/api/npm/npm/ ./install.sh --local
$env:UNSLOTH_NPM_REGISTRY='https://artifactory.example.com/api/npm/npm/'; .\install.ps1 --local
Cap Unsloth's native CPU thread pools on high-core hosts: UNSLOTH_CPU_THREADS=8 unsloth studio -p 8888.
Vulkan, custom llama.cpp backends:
You can force the backend during installation:
export UNSLOTH_LLAMA_CPP_BACKEND=vulkan   # or cpu, cuda, rocm, auto
curl -fsSL https://unsloth.ai/install.sh | sh
$env:UNSLOTH_LLAMA_CPP_BACKEND="vulkan"   # or cpu, cuda, rocm, auto
irm https://unsloth.ai/install.ps1 | iex
audio.cpp audio engine:
Setup also installs audio.cpp (prebuilt by unslothai/audio.cpp), which runs the audio.cpp speech, music and speech-to-text models on the Audio page, in Voice settings and behind /v1/audio/*. It is optional and never blocks setup:
UNSLOTH_SKIP_AUDIO_CPP_INSTALL=1skips it.UNSLOTH_AUDIO_CPP_ACCELERATOR=cpu(orcuda,vulkan,metal) picks the bundle instead of auto-detecting.AUDIOCPP_SERVER_PATH=/path/to/audiocpp_serveruses your own build.
Uninstall
MacOS, WSL, Linux: curl -fsSL https://raw.githubusercontent.com/unslothai/unsloth/main/scripts/uninstall.sh | sh
Windows (PowerShell): irm https://raw.githubusercontent.com/unslothai/unsloth/main/scripts/uninstall.ps1 | iex
For more info, see our docs.
Deleting model files
You can delete old model files either from the bin icon in model search or by removing the relevant cached model folder from the default Hugging Face cache directory. By default, HF uses:
MacOS, Linux, WSL: ~/.cache/huggingface/hub/
Windows: %USERPROFILE%\.cache\huggingface\hub\
💚 Community and Links
| Type | Links |
|---|---|
 Discord |
Join Discord server |
 r/unsloth Reddit |
Join Reddit community |
| 📚 Documentation & Wiki | Read Our Docs |
 Twitter (aka X) |
Follow us on X |
| 🔮 Our Models | Unsloth Catalog |
| ✍️ Blog | Read our Blogs |
Citation
You can cite the Unsloth repo as follows:
@software{unsloth,
  author = {Daniel Han, Michael Han and Unsloth team},
  title = {Unsloth},
  url = {https://github.com/unslothai/unsloth},
  year = {2023}
}
If you trained a model with 🦥Unsloth, you can use this cool sticker! 
License
Unsloth uses a dual-licensing model of Apache 2.0 and AGPL-3.0. The core Unsloth package remains licensed under Apache 2.0, while certain optional components, such as the Unsloth Studio UI are licensed under the open-source license AGPL-3.0.
This structure helps support ongoing Unsloth development while keeping the project open source and enabling the broader ecosystem to continue growing.
Thank You to
- The llama.cpp library that lets users run and save models with Unsloth
- The Hugging Face team and their libraries: transformers and TRL
- The Pytorch and Torch AO team for their contributions
- NVIDIA for their NeMo DataDesigner library and their contributions
- And of course for every single person who has contributed or has used Unsloth!